Amazon Builds Home Robotics Team for New-to-World Robot
Source: Unite.AI CNBC reported on November 8, 2026 that Amazon had assembled a home-robotics team over the preceding...
What Is AI Red Teaming? How Experts Stress-Test Models and Agents
Source: Unite.AI AI red teaming is adversarial testing that actively searches for ways a model or AI system...
Google AI Releases Elephant-Goldfish Model Plugin for Spec-First Coding
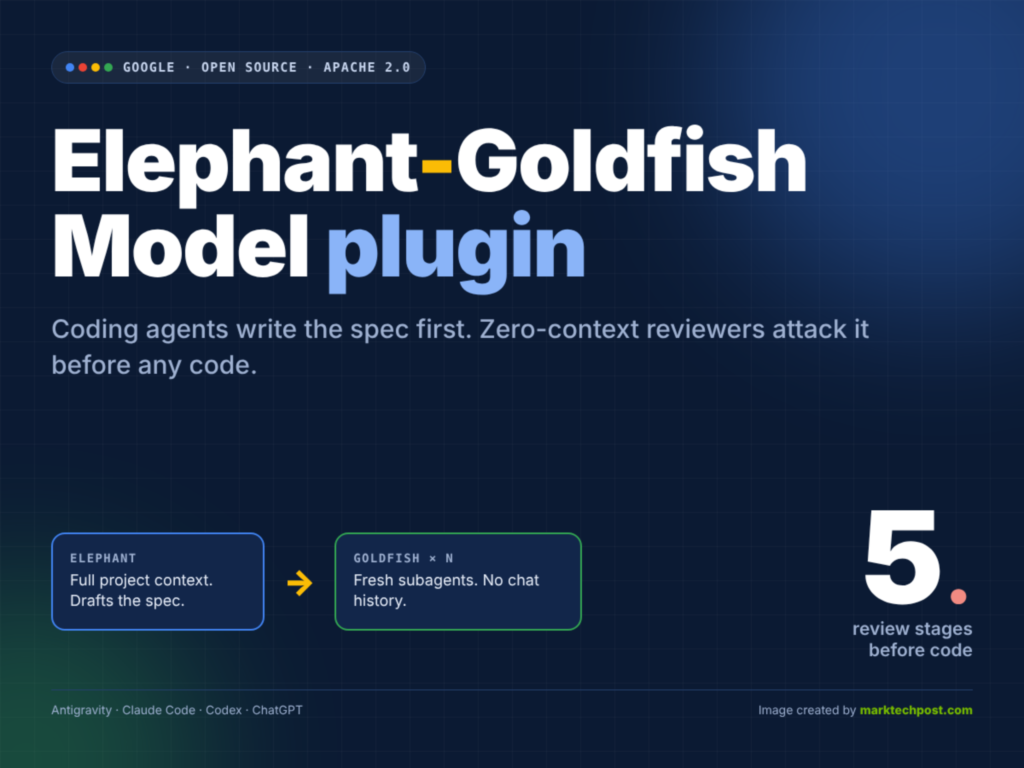
Source: MarkTechPost Google has open-sourced the Elephant-Goldfish Model (EGM) plugin, a design-and-review layer for AI coding agents. The...

Which Routing Does Each MoE Model Use? DeepSeek, Qwen, Mixtral, Llama 4, gpt-oss Compared
Source: MarkTechPost Open Mixture-of-Experts (MoE) models share one idea but disagree on almost every routing detail. Expert counts...

MoE Routing Strategies Explained: Top-K, Expert-Choice, Sigmoid Gating and Dynamic Routing (2026 Guide)
Source: MarkTechPost Every Mixture-of-Experts (MoE) model repeats one decision for every token: which experts should process it. That...
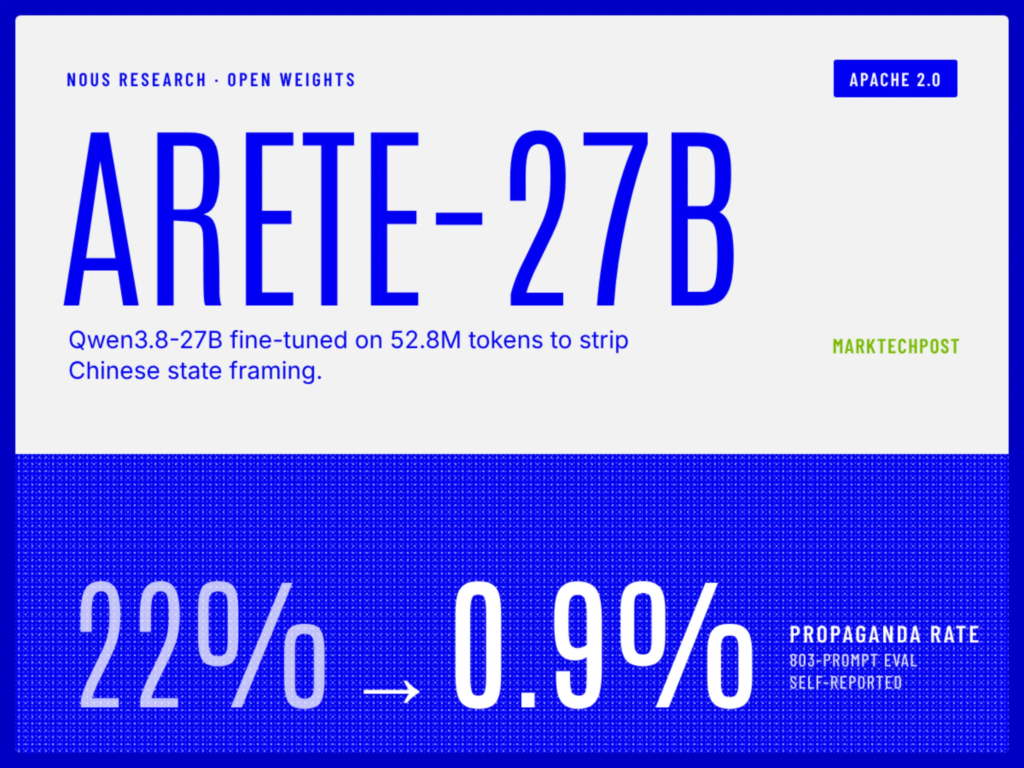
Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9%
Source: MarkTechPost Nous Research has released Arete-27B, a supervised fine-tune of Alibaba’s Qwen3.8-27B. Arete-27B is a 27B open-weight...
How to Run NVIDIA Dory 4B with llama.cpp: Loop by Loop Guide
Source: MarkTechPost In this tutorial, we work with Dory 1.0 4B, a small reasoning model from NVIDIA’s Nemotron...
Book Review: Forward Deployed: Inside the Palantir Framework That Solved Enterprise AI by Riste Gramatikov
Source: Unite.AI Ever since The Lean Startup by Eric Ries was published in 2011, prevailing wisdom in the...
Anthropic’s Planned IPO Puts Public Trust and Data Centers in Focus
Source: Unite.AI CNBC reported on November 7, 2026 that Anthropic is likely targeting mid-November 2026 for a Nasdaq...
What Is Model Distillation? How Large AI Models Teach Smaller Ones
Source: Unite.AI Model distillation transfers behavior from a larger or more capable teacher into a smaller student model...