Source: MarkTechPost
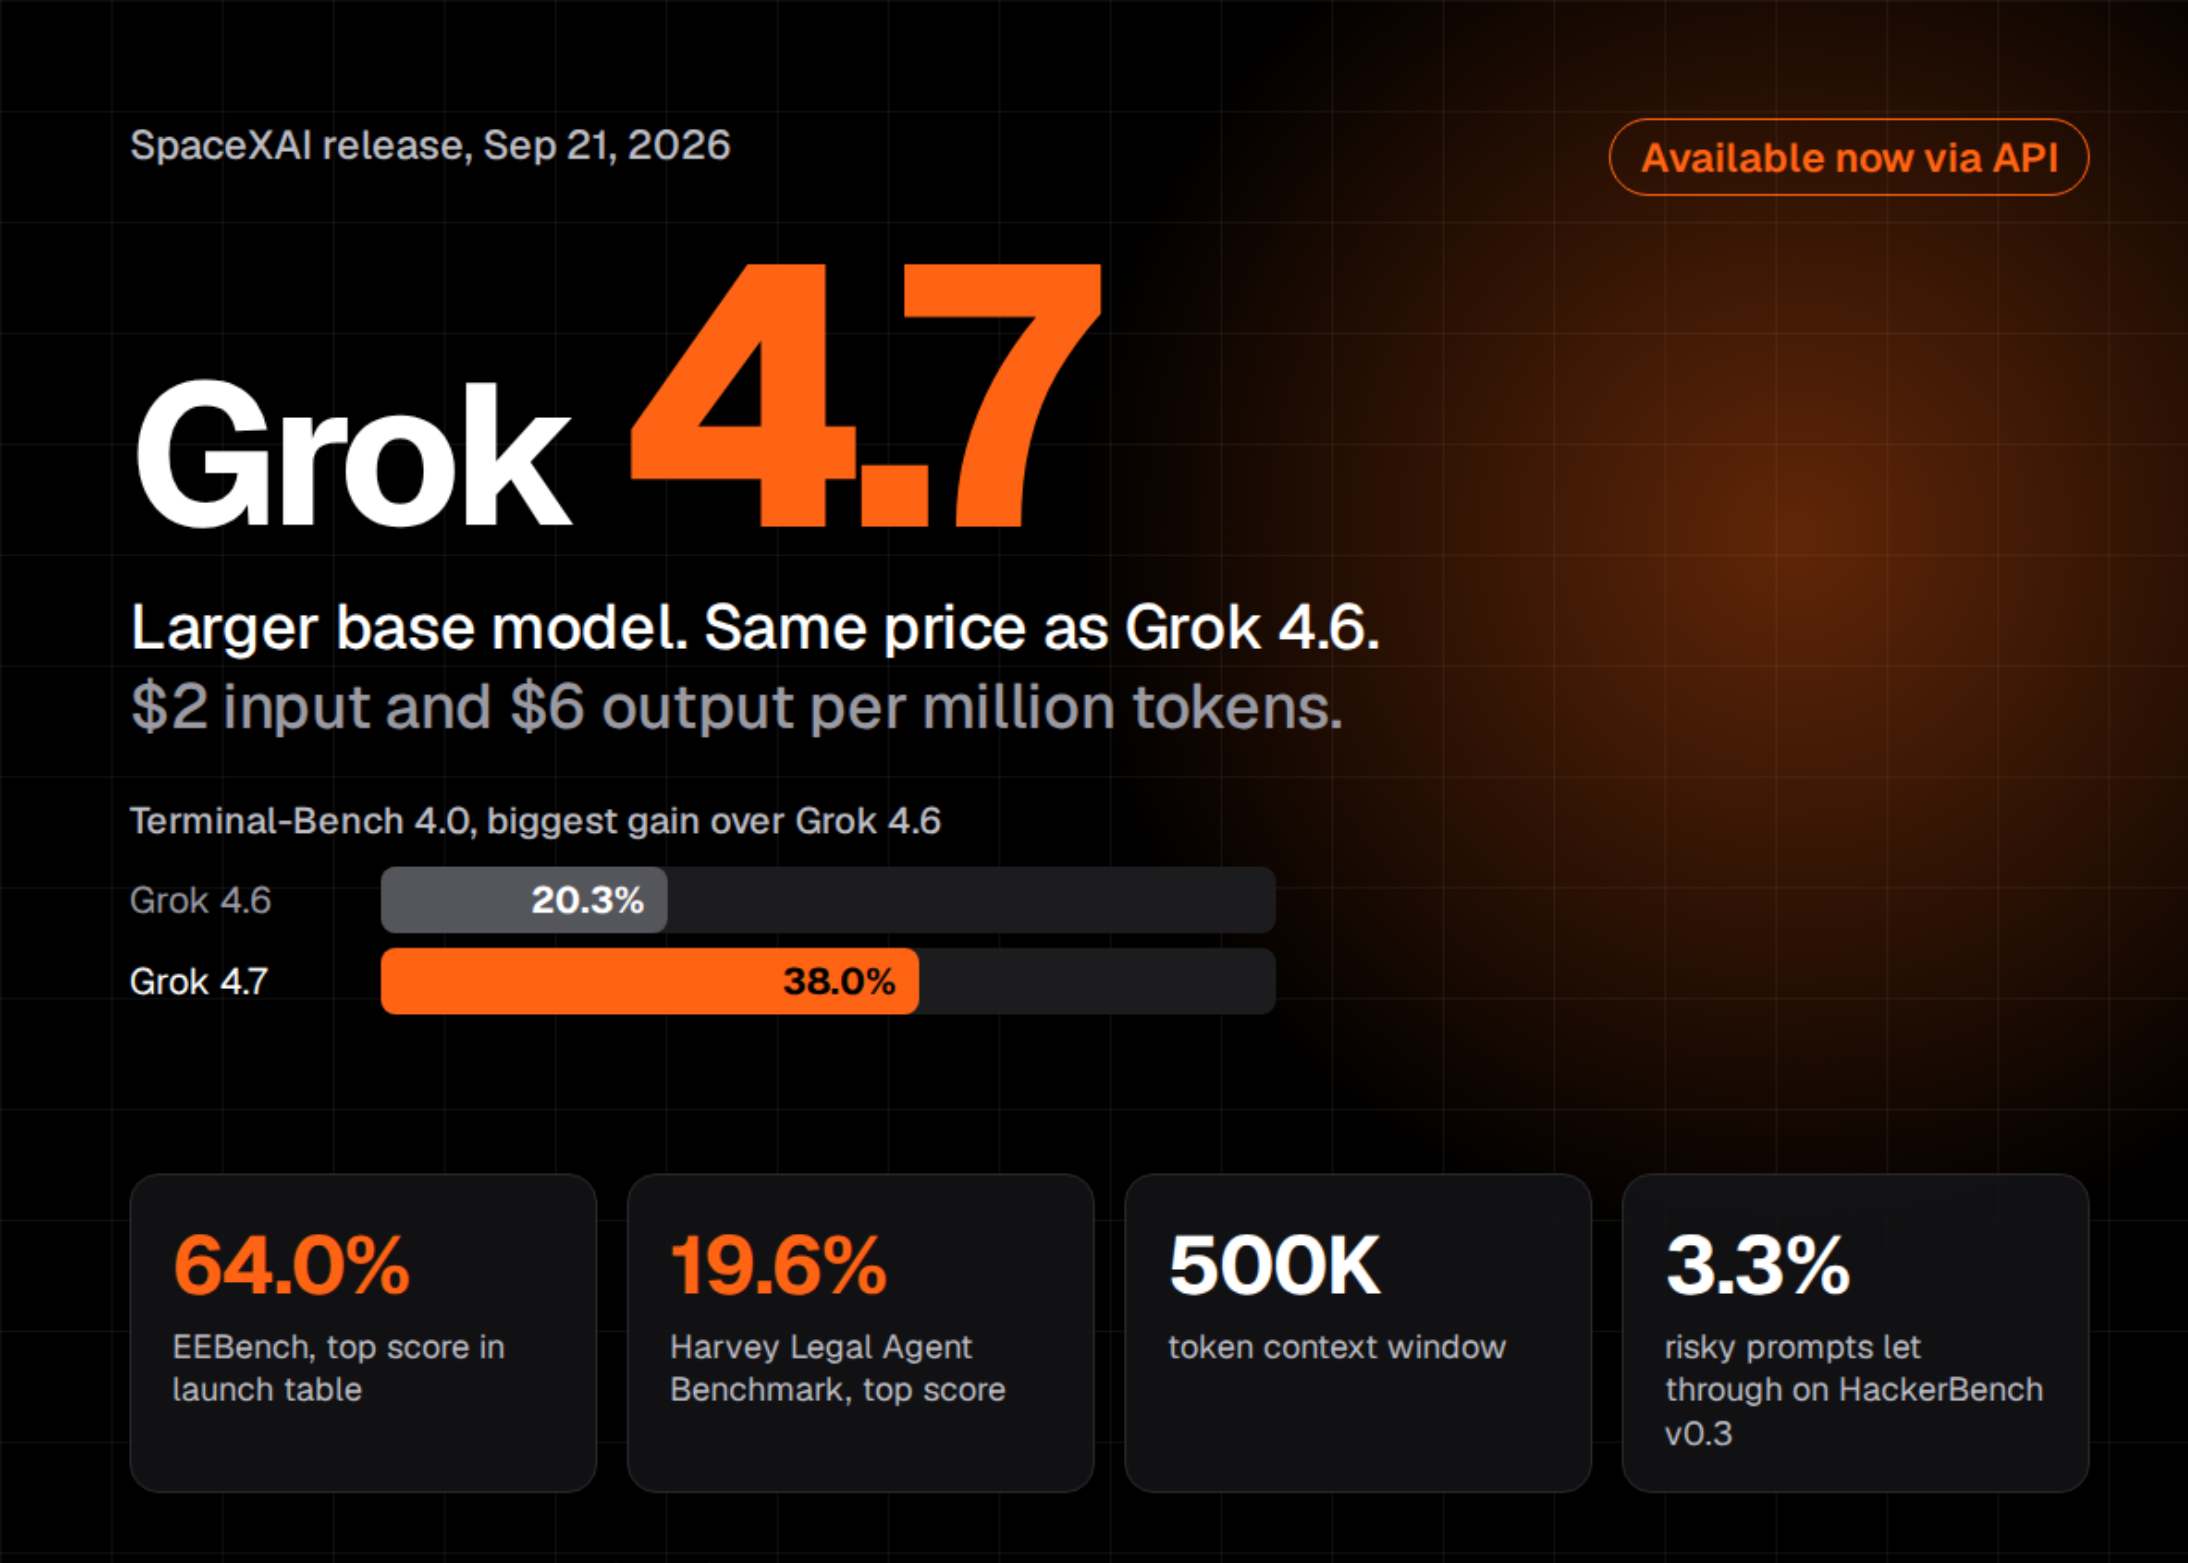
SpaceXAI has released Grok 4.7, its new flagship model for coding, agentic tasks, and knowledge work. Grok 4.7 is built on a larger base model and a longer reinforcement learning run. It still ships at the same price and speed as Grok 4.6.
Is it deployable? Yes, as a hosted model. You can call grok-4.7 today through the xAI API, Cursor, Grok Build, OpenRouter, Vercel, and Cloudflare.
What Changed Under the Hood
SpaceXAI lists 4 changes over Grok 4.6:
- A new, larger base model: Grok 4.7 does not reuse the Grok 4.6 base.
- A longer RL run on harder tasks: The task mix is weighted toward problems that take many hours to complete.
- Better self-verification and long-context handling: The company says the model checks its own work more carefully.
- Native Grok Bot harness support: It was trained to understand the Grok Bot harness for conversational and knowledge work.
The developer docs list the API specs:
| Property | Value |
|---|---|
| Model name | grok-4.7 |
| Context window | 500,000 tokens |
| Knowledge cutoff | May 2026 |
| Modalities | Text and image input, text output |
| Reasoning effort | low, medium, high (default), xhigh |
| APIs | Responses API, Chat Completions |
| Tools | Function calling, web search, X search, code execution |
Benchmarks
The launch table compares Grok 4.7 at xHigh effort with Grok 4.6 High, GPT-5.6 Sol Max, and Fable 5.1 Max. The Grok 4.7 DeepSWE score was run at high effort. All scores are vendor-reported.
| Benchmark | Grok 4.7 xHigh | Grok 4.6 High | GPT-5.6 Sol Max | Fable 5.1 Max |
|---|---|---|---|---|
| Input price ($/M) | $2 | $2 | $4 | $10 |
| Output price ($/M) | $6 | $6 | $20 | $50 |
| CursorBench 4.0 | 46.3% | 40.4% | 41.7% | 51.8% |
| DeepSWE v1.1 | 71.0%* | 65.2% | 72.7% | 70.0% |
| EEBench | 64.0% | 53.0% | 39.4% | 56.4% |
| AA Briefcase v1.1 | 1,657 | 1,546 | 1,487 | 1,678 |
| Terminal-Bench 4.0 | 38.0% | 20.3% | 37.3% | 57.9% |
| Harvey Legal Agent Benchmark | 19.6% | 15.8% | 2.5% | 6.7% |
| HealthBench Professional | 56.7% | 48.5% | 60.5% | 62.1% |
*High effort
Grok 4.7 improves on Grok 4.6 in every row. The largest jump is on Terminal-Bench 4.0, from 20.3% to 38.0%. EEBench rose 11 points to 64.0%, the top score in the table. On Harvey’s legal agent benchmark, Grok 4.7 scored 19.6% against 6.7% for Fable 5.1 Max.
Grok 4.7 does not lead across the board. Fable 5.1 Max tops 4 of 7 benchmarks, including a 57.9% Terminal-Bench score. GPT-5.6 Sol Max holds the top DeepSWE v1.1 result at 72.7%.
Price is the other axis. Fable 5.1 Max costs 5x more on input and about 8.3x more on output. GPT-5.6 Sol Max costs 2x more on input and about 3.3x more on output. On a CursorBench 4.0 cost-per-task chart, SpaceXAI places Grok 4.7 at the frontier in price-performance.
On GDPval, which tests professional knowledge work, Grok 4.7 xhigh scored 1,695 Elo. That is up from 1,605 for Grok 4.6 high. Fable 5.1 max leads at 1,735, and GPT-6 Astra max scored 1,542. SpaceXAI also says Grok 4.7 is better at creating documents and presentations.
Safety and Cybersecurity
Grok 4.7 ships with an entirely new safeguard stack. SpaceXAI calls it the strongest model it has tested on refusals and jailbreak resistance. It topped LatchBio’s biosafety benchmark at 62.4%.
On HackerBench v0.3, SpaceXAI’s own benchmark for risky and malicious cyber tasks, the model let 3.3% of risky dual-use prompts through. The company says it rarely blocks legitimate security work. Select cybersecurity partners now get invite-only access to its red-team capabilities for defense research.
Pricing and Availability
Grok 4.7 costs $2 per million input tokens and $6 per million output tokens. It is available in Cursor on all plans and is the default model in Grok Build. It is also served through the Grok API, OpenRouter, Vercel, and Cloudflare.
Grok 4.7 Fast is the same model on faster infrastructure, with twice the output speed at twice the price. The docs say it runs only in Cursor and Grok Build, not on the public xAI API. It is also excluded from Grok Build’s free tier.
A US regional endpoint at https://us.api.x.ai/v1 keeps inference in the United States at a 10% premium. SpaceXAI recommends setting a prompt_cache_key for reliable cache hits.
import os from xai_sdk import Client from xai_sdk.chat import user client = Client(api_key=os.getenv("XAI_API_KEY")) chat = client.chat.create(model="grok-4.7") chat.append(user("Explain this repo.")) print(chat.sample().content)Interactive Explainer
Key Takeaways
- Grok 4.7 keeps Grok 4.6 pricing at $2 input and $6 output per million tokens.
- It leads the launch table on EEBench (64.0%) and Harvey Legal Agent Benchmark (19.6%).
- Fable 5.1 Max still leads on 4 of 7 benchmarks, including Terminal-Bench 4.0.
- The API offers a 500,000-token context window and 4 reasoning levels up to xhigh.
- Only 3.3% of risky dual-use prompts passed on SpaceXAI’s HackerBench v0.3.
Check out the announcement, docs, and X post. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us

Michal Sutter
Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.