Source: Unite.AI
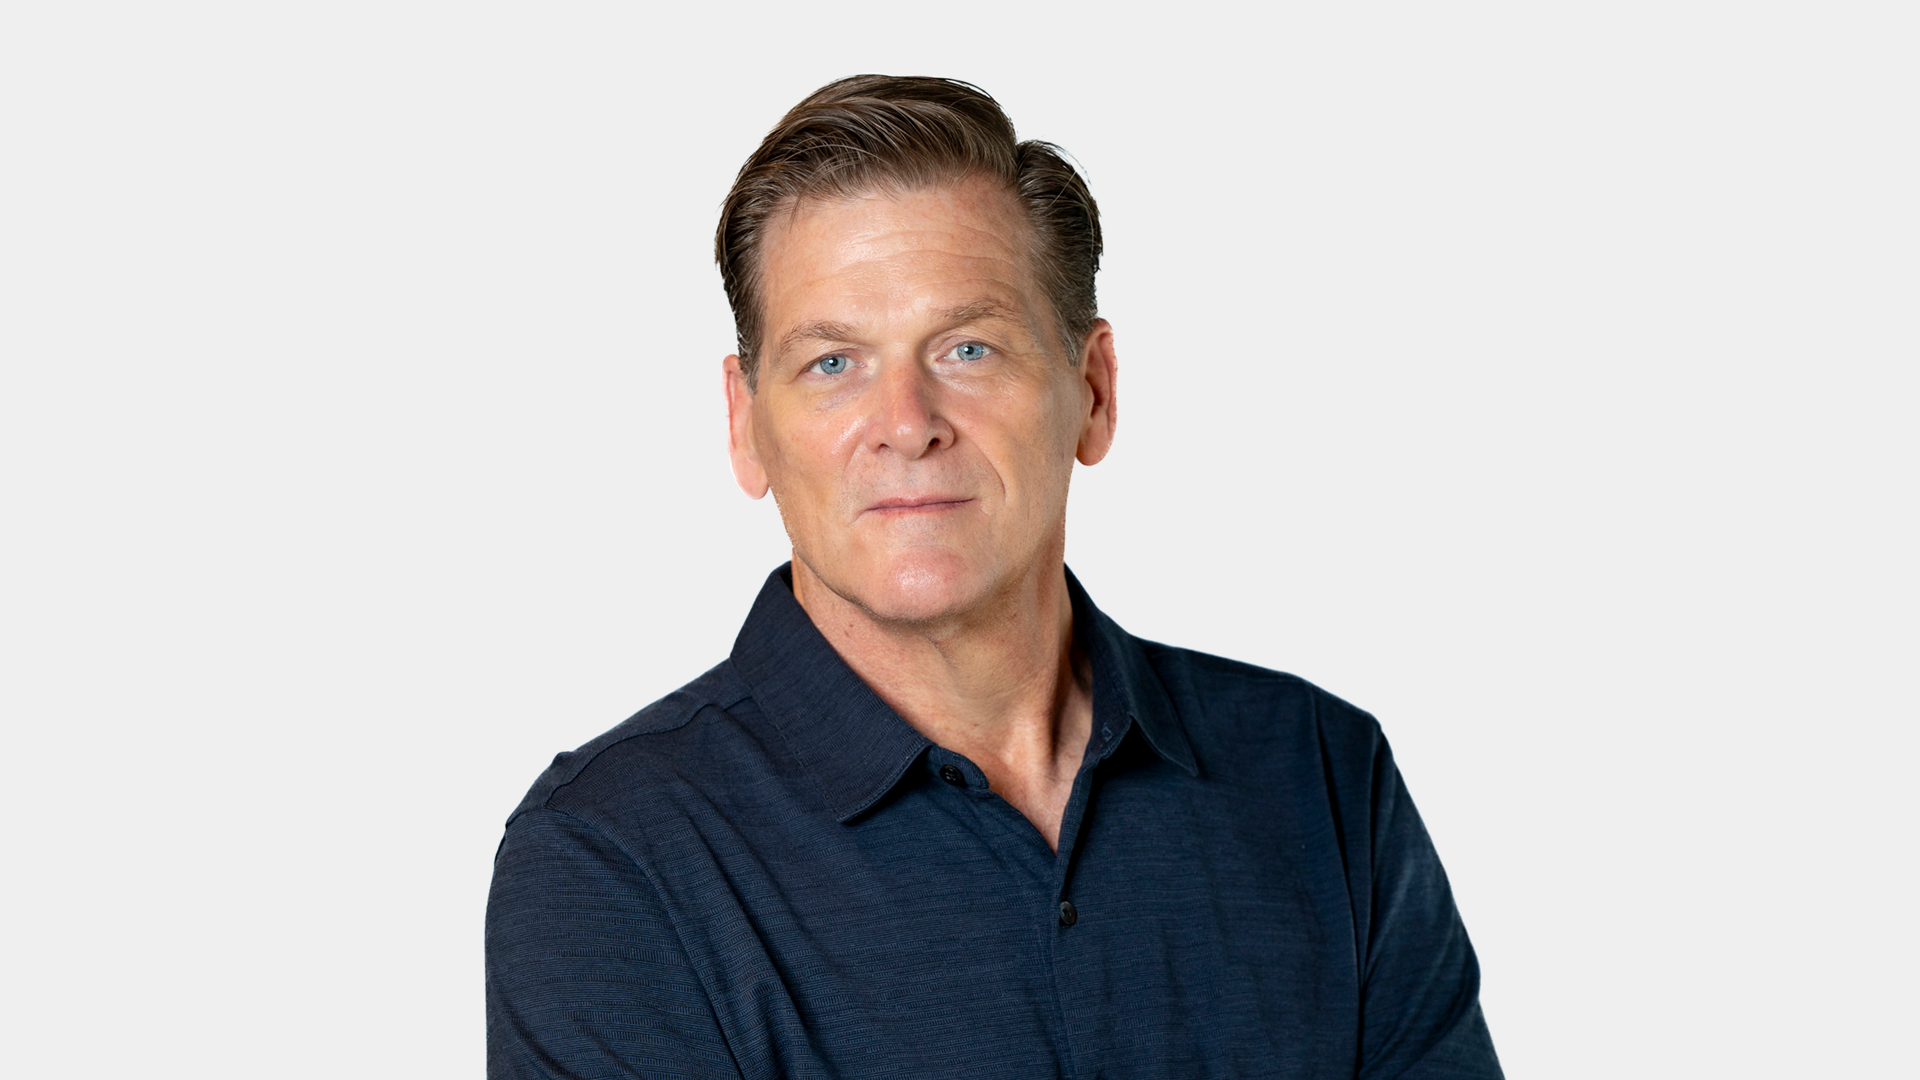
Scott Ernst is Chief Executive Officer of Vyond and a veteran technology leader with more than two decades of experience scaling SaaS, AI, data, and marketing technology companies. He previously served as CEO of Uptempo, Drift, Tubular Labs, and Macromill, where he led the company through its initial public offering and its growth into a global digital insights leader. Across these roles he has driven significant growth, transformation, strategic acquisitions, and successful exits. Earlier in his career, he helped build Compete from an early-stage startup into a global digital marketing business generating more than $100 million in annual revenue. Scott is known for developing high-performing teams, sharpening go-to-market strategy, and translating product innovation into durable customer and shareholder value.
Vyond helps organizations transform enterprise knowledge into clear, engaging visual communication that drives action. Its AI-powered video creation platform combines instant video generation, full-featured editing, and enterprise-grade controls to help teams accelerate onboarding, simplify compliance, enable sales, educate customers, and communicate consistently at scale. For nearly 20 years, Vyond has helped businesses move from information to understanding—and from understanding to measurable outcomes. Today, more than 15,000 organizations, including 65% of the Fortune Global 500, rely on Vyond, with customers creating more than 40 million videos since the company’s founding in 2007.
You’ve repeatedly led technology companies through major transitions, from helping scale Compete from an early stage startup through acquisition, to taking Macromill through an IPO, and later repositioning Drift around AI before its acquisition by Salesloft. As you take the helm at Vyond during another major technology shift, what lessons from those experiences are shaping how you approach the AI era?
The pattern I’ve seen across every one of those transitions is that the technology shift is rarely the hard part, the hard part is getting an organization to move together once the shift is obvious. At Compete, the lesson was about discipline: building a category leader from a small base takes relentless focus on the few things that actually move the business, not chasing every opportunity. At Macromill, scaling globally and taking the company public taught me that growth without operating rigor eventually breaks…you need the reporting, the forecasting, and the governance to scale as fast as the business does.
Drift is the one that maps most directly to what’s happening now. When ChatGPT launched, we had already built our own proprietary AI product, and our instinct was to protect it. Instead, we made the harder call to open up and reposition the whole company around generative AI, because we believed the market was moving faster than our moat could defend. That wasn’t a product decision, it was a leadership decision about conviction and timing.
The lesson I’ve carried into Vyond is that during a genuine platform shift, the companies that win aren’t the most cautious ones or the most reckless ones, they’re the ones that get their whole organization aligned around a clear point of view fast, and then execute with real urgency. That’s exactly the process we’re running now: understanding what’s true today, forming real conviction about where the market is going, and getting the entire company moving in the same direction before the window closes.
Generative AI has made it dramatically easier for enterprises to produce content, but you’ve argued that the bigger challenge is now operationalizing knowledge. What does that mean in practice, and why do you believe content generation alone solves only a small part of the problem?
Generative AI solved the hardest historical bottleneck in content creation: it used to require a specialist, a production workflow, and real lead time. Now nearly anyone in an organization can produce something in minutes. That’s a genuine unlock, but it also means every function across marketing, HR, sales, IT, and L&D is now creating content independently, often about the same underlying knowledge, using different tools, with no shared system of record.
Operationalizing knowledge is less about generating more content and more about making sure people can find and use the correct information: it’s knowing where the trusted, current version of something lives, who owns it, whether it’s approved, and how it moves into the workflows where people actually need it: the LMS, the CRM, the onboarding checklist, and the compliance tracker. Without that layer, you get what I’d call Communication Chaos: content is duplicated, brand standards drift, teams recreate work that already exists, and nobody can say with confidence which version is the truth. A lot of that chaos starts even earlier than people realize, before a single asset gets made, when nobody actually confirmed the audience, the goal, or the source material the request was supposed to be grounded in.
Content generation answers the question, ‘Can we make this quickly?,’ which is a real problem that AI has largely solved. Operationalizing knowledge answers ‘can the right person find the right, trusted version of this at the moment they need it, in the tool they’re already using,’ and that second problem is bigger, more structural, and far from solved industry wide. It’s the actual opportunity in front of us.
Enterprises are accumulating enormous volumes of documents, data, AI generated summaries and institutional knowledge. Where do you see the biggest breakdown occurring between having access to that information and actually communicating it in a way employees can understand and act on?
The breakdown isn’t access…most enterprises already have more information than any one person can process. It’s transformation and trust. Knowledge sits in dense, static formats such as PDFs, decks, wikis, and policy documents, built to be stored and searched, not understood quickly. Turning that into something a person can actually absorb and act on requires a transformation step that most organizations don’t systematically invest in.
I saw this clearly in a conversation with a customer’s VP of enterprise marketing technology at a Fortune 100 technology company. His problem wasn’t a lack of information, it was that different parts of a very large organization were solving the same communication problems in isolated, inconsistent ways, so knowledge that existed somewhere in the company never reliably reached the people who needed it, in a form they could use. As he put it, in a company that large, the left hand and the right hand simply don’t communicate.
That’s the real gap: enterprises have plenty of data and too little insight. The fix isn’t more content or more storage, it’s a discipline and, increasingly, a system for converting raw institutional knowledge into clear, visual, trusted communication and routing it into the workflows where decisions actually get made.
As AI agents become capable of autonomously transforming company knowledge into training, sales enablement, compliance or internal communications, what should remain under human control, and where can enterprises safely allow agents to operate independently?
My general rule is that agents should own the labor, and humans should own the judgment, especially anywhere a mistake carries real consequence. For lower stakes, high volume, repetitive work such as first drafts, formatting knowledge into a new format, adapting existing approved content for a new language or region, or refreshing a training module when a source document changes, agents can and should operate with a lot of autonomy. That’s exactly the kind of work that consumes enormous amounts of time today for very little strategic value.
Where human control has to remain firm is anywhere the content carries legal, regulatory, safety, or brand risk. In those cases, a human needs to be the final checkpoint before anything goes live, and the underlying source material needs to be fully traceable.
We saw this play out directly with a defense sector customer of ours. Their security team initially wouldn’t approve AI in their workflow at all, given the sensitivity of their work. The resolution wasn’t giving the agent more autonomy, it was building the right guardrails: a custom agreement guaranteeing their data would never train external models, and clear checkpoints where their own teams retained approval. That’s the model I’d generalize: agent autonomy scales with how reversible and low risk the task is, and human control scales with how much trust, compliance, or brand exposure is on the line.
Brand governance becomes much more complicated when thousands of pieces of content can be generated automatically. What technical and organizational safeguards will enterprises need to ensure AI generated communications remain accurate, consistent and aligned with company policies?
Technically, the safeguards that matter most are the ones that keep AI generated output grounded in a company’s own approved source material and brand system, rather than letting it generate freely. Style guides, brand assets, and customization guardrails need to be enforced by the platform itself, not left to individual users to remember. That means the approved logo, colors, templates, and reference footage need to live inside the platform itself, so every generated piece pulls from the same source, rather than whatever version happens to be sitting on someone’s desktop that week. Version control and audit trails matter just as much: if a piece of content is generated, edited, or approved, an enterprise needs to be able to trace it back to who requested it, what source it came from, and who signed off. It also means giving reviewers and stakeholders, not just the person driving the tool, a way to comment and sign off inside that same workflow, so approval doesn’t happen in a separate email thread that breaks the very audit trail you’re trying to build.
Organizationally, the safeguard is clear ownership. The enterprises we work with that govern this well have moved away from every team independently adopting its own tools and process, and instead treat their communication platform the way they’d treat a system of record…access is granted deliberately, usage is monitored in aggregate, and there’s a small governance function responsible for the standards everyone builds against. We’ve seen large organizations explicitly evaluate whether a platform can become their standard, company wide system for this exact reason: it’s the only way to get consistency at scale instead of thousands of independently ‘good enough’ pieces of content that don’t actually agree with each other.
The underlying principle is the same one that’s always applied to brand governance, it’s just operating at a much higher volume and speed now, which means the guardrails have to be built into the system, not enforced after the fact.
Hallucinations are concerning in a chatbot, but potentially much more consequential when incorrect information is turned into an authoritative looking training or compliance video. How should enterprises think about grounding, verification and provenance as AI generated communication becomes more automated?
You’re right that the stakes are different. A hallucinated answer in a chat window gets questioned in the moment. A hallucinated fact embedded in a polished, professionally produced compliance video carries an authority that makes people less likely to question it, which is exactly backward from where the scrutiny should be highest.
The first principle has to be grounding: AI generated communication should be constrained to the source material an enterprise actually provides…its own documents, its own policies, its own approved data, rather than the model’s general knowledge.
The second is provenance: every piece of generated content should be traceable back to the specific source it was built from, so if something is wrong, you can find out exactly where it came from and fix it at the source, not just patch the output.
The third is verification: checkpoints built into the workflow itself, not bolted on afterward. A human reviewer should see the intermediate steps, not just the finished, polished video, because polish is precisely what makes errors harder to catch. In practice that means reviewing a complete outline or draft cut scene by scene before committing to a final, more expensive render, so catching a wrong fact or an off brand claim while it’s still cheap and easy to fix. This is one of the areas where enterprises are right to be cautious, and it’s why the platforms that win enterprise trust here won’t be the ones that are fastest, they’ll be the ones that make grounding, traceability, and review a structural part of how the system works, not an optional setting
The fourth layer is ongoing evaluation, not just a final review. In an agentic system, checking the finished video isn’t enough. We want visibility into how the agent got there. We continuously monitor the agent’s outputs and the decisions it makes along the way, checking that they stay aligned with the customer’s source documents, knowledge base, and original intent. That lets us catch drift or lower-quality output while a video is still being generated, rather than discovering a problem only after it’s already finished.
AI systems are increasingly being connected directly to enterprise knowledge bases and business workflows. Do you expect the next generation of communication platforms to become an interface between enterprise data, AI agents and employees rather than simply tools for creating content?
Yes, and I think that shift is already underway. Content creation was the first, most obvious problem for AI to solve because it was the most visible bottleneck. But once creation stops being the constraint, the more valuable position is sitting between an enterprise’s knowledge…its CRM, its LMS, its policy systems, its internal wikis, and the people who need he that knowledge translated into something they can actually use.
That’s a meaningfully different role than a creation tool. A creation tool waits for someone to bring it a request. An interface layer sits inside the workflows where knowledge already lives, understands what’s changed, and helps route the right communication to the right person without someone having to initiate it every time.
We’re already seeing the early signs of enterprises wanting exactly this. Large customers increasingly aren’t asking us to be a video tool for one team, they’re asking whether we can be the standard system for their whole organization. Turning institutional knowledge into communication would enable employees well outside the core creative team, legal, compliance, regional teams, frontline managers, to weigh in without needing a full license or a steep learning curve. That’s the shift from content creation to communication infrastructure, and it’s the direction I expect the entire category to move.
That shift is also being accelerated by emerging open protocols like MCP and A2A. MCP gives AI agents a standardized way to pull trusted context from an enterprise’s own tools and systems of record, while A2A lets specialized agents from different platforms work together. In practical terms, that means a platform like ours doesn’t need to own every workflow or every piece of enterprise data to be useful. It can plug into the systems a company already trusts, collaborate with other agents where it makes sense, and focus on what we do best: turning that context into communication people can actually understand and act on. That’s the shift from content creation to communication infrastructure, and it’s the direction I expect the entire category to move.
Vyond already serves organizations across learning and development, HR, sales enablement, compliance and internal communications. Which of these areas do you believe will be transformed most significantly by agentic AI, and what might those workflows look like once agents become more capable?
I’d point to compliance and learning and development as the two with the most room to change, precisely because they’re the two most burdened by staleness today. Compliance training is usually built once and updated on a slow annual or biannual cycle, even though policies, regulations, and risks change continuously. Once agents can reliably monitor a source policy document and understand what changed, compliance content can move from a periodic production project to something that’s kept continuously current, which is a real risk reduction for the enterprise, not just an efficiency gain. Increasingly, that also means the content itself needs to carry a clear, auditable record that it was AI assisted, since regulators and enterprise buyers alike are starting to expect that kind of disclosure as standard practice, not an afterthought.
L&D has a similar dynamic, but the opportunity is personalization rather than just currency: instead of one training module built for an average learner, agents can help tailor pacing, examples, and even format to the role and the individual, while staying grounded in the same approved source material and instructional design standards. For global organizations, that increasingly includes language and voice too, so the same training reaches a plant floor in Brazil or a sales team in Japan in a form that actually feels local, not just subtitled.
Sales enablement and internal communications will change too, but I’d describe that change as speed and relevance more than structural transformation…getting the right message to the right rep or the right team faster, in a format suited to how they actually consume information. The common thread across all of these areas is the same: agentic AI doesn’t just make each of these faster, it makes them capable of staying current in a way that’s simply not realistic with manual production cycles today.
Looking further ahead, if enterprises become capable of continuously converting internal knowledge into personalized, up to date communication for every employee, how could that change the way organizations train people, share expertise and ultimately operate?
If that becomes real, and I believe it will, it changes the operating rhythm of a company, not just its training function. Today, most organizations communicate in batches: an annual compliance cycle, a quarterly companywide meeting, an onboarding packet built once and reused for years. That’s a function of how expensive and slow communication has historically been to produce, not a reflection of how fast the business actually changes.
A world where knowledge continuously converts into personalized, current communication for every employee means training stops being an event and becomes a constant, adaptive stream…someone gets the update, in the format and depth that’s right for their role, the moment it’s relevant, not months later in a batch. Expertise stops being locked inside the individuals who happen to hold it and becomes something the organization can systematically distribute and keep fresh.
The outcome I keep coming back to is time. Every minute an organization spends today searching for the right information, recreating something that already exists, or correcting a message that went out stale or inconsistent is time not spent executing. If enterprises can genuinely close that gap between knowledge and understanding, continuously and at scale, the organizations that get there first won’t just communicate better, they’ll simply move faster than the ones still operating in batches.
Thank you for the great interview, readers who wish to learn more should visit Vyond.