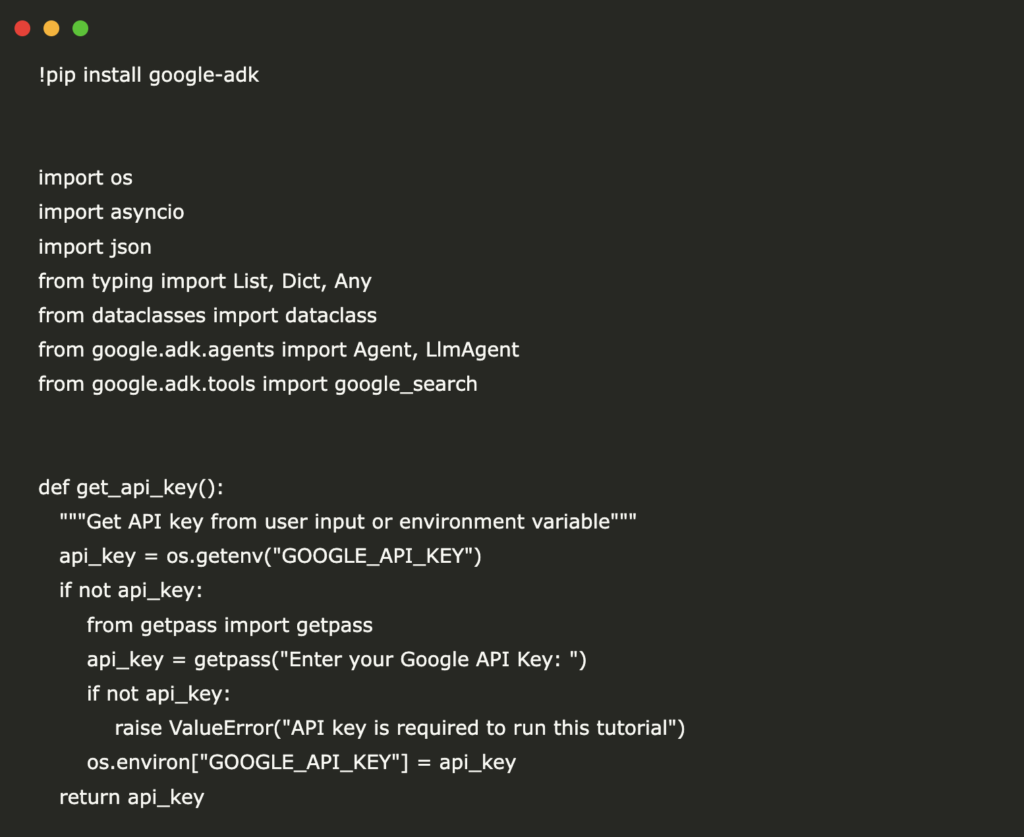
A Coding Guide to Build a Scalable Multi-Agent System with Google ADK
Source: MarkTechPost In this tutorial, we explore the advanced capabilities of Google’s Agent Development Kit (ADK) by building...
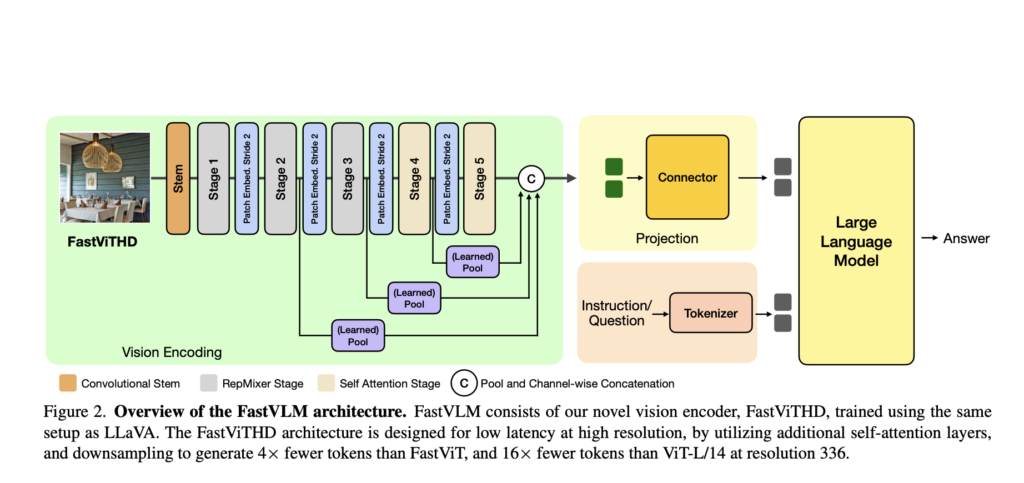
Apple Researchers Introduce FastVLM: Achieving State-of-the-Art Resolution-Latency-Accuracy Trade-off in Vision Language Models
Source: MarkTechPost Vision Language Models (VLMs) allow both text inputs and visual understanding. However, image resolution is crucial...
Is Vibe Coding Safe for Startups? A Technical Risk Audit Based on Real-World Use Cases
Source: MarkTechPost Introduction: Why Startups Are Looking at Vibe Coding Startups are under pressure to build, iterate, and...
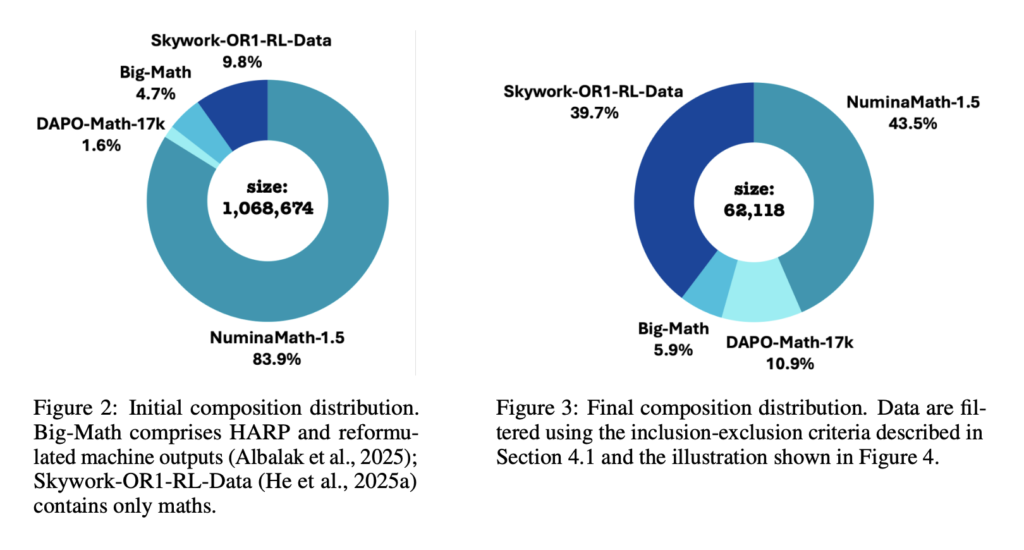
MiroMind-M1: Advancing Open-Source Mathematical Reasoning via Context-Aware Multi-Stage Reinforcement Learning
Source: MarkTechPost Large language models (LLMs) have recently demonstrated remarkable progress in multi-step reasoning, establishing mathematical problem-solving as...
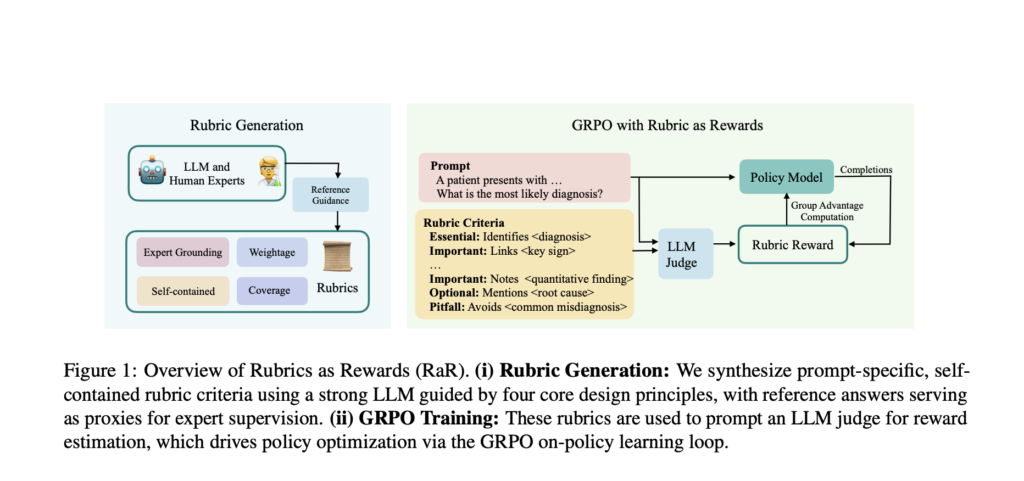
Rubrics as Rewards (RaR): A Reinforcement Learning Framework for Training Language Models with Structured, Multi-Criteria Evaluation Signals
Source: MarkTechPost Reinforcement Learning with Verifiable Rewards (RLVR) allows LLMs to perform complex reasoning on tasks with clear,...
New algorithms enable efficient machine learning with symmetric data
Source: MIT News – Artificial intelligence If you rotate an image of a molecular structure, a human can...
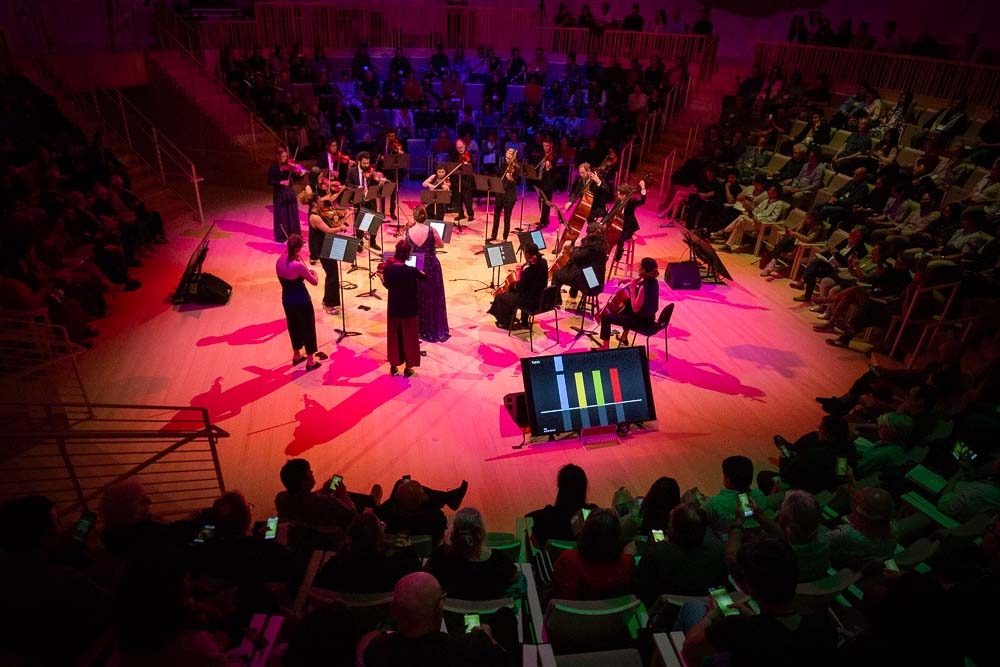
“FUTURE PHASES” showcases new frontiers in music technology and interactive performance
Source: MIT News – Artificial intelligence Music technology took center stage at MIT during “FUTURE PHASES,” an evening...
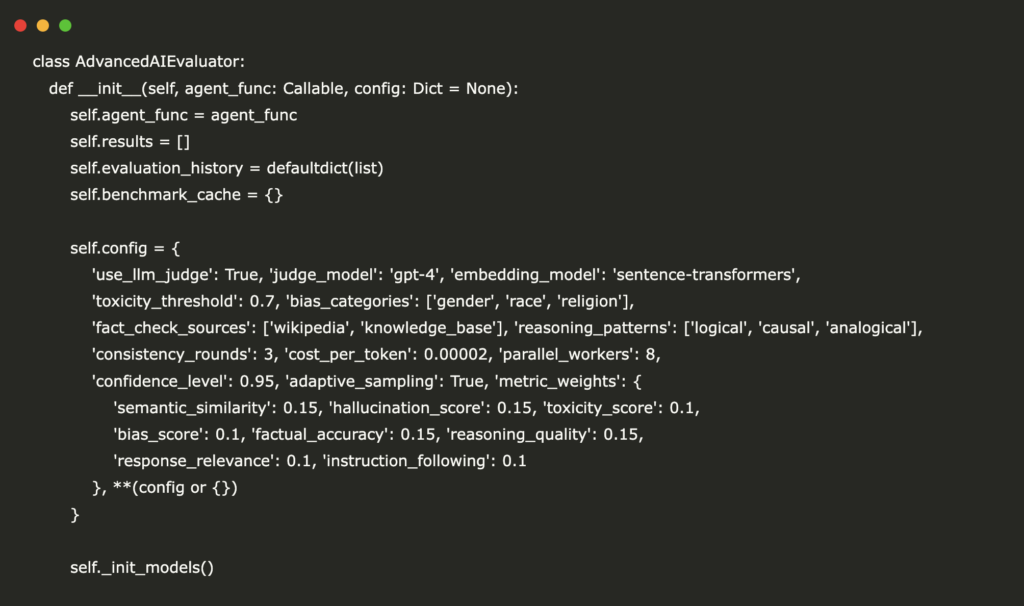
Building a Comprehensive AI Agent Evaluation Framework with Metrics, Reports, and Visual Dashboards
Source: MarkTechPost In this tutorial, we walk through the creation of an advanced AI evaluation framework designed to...
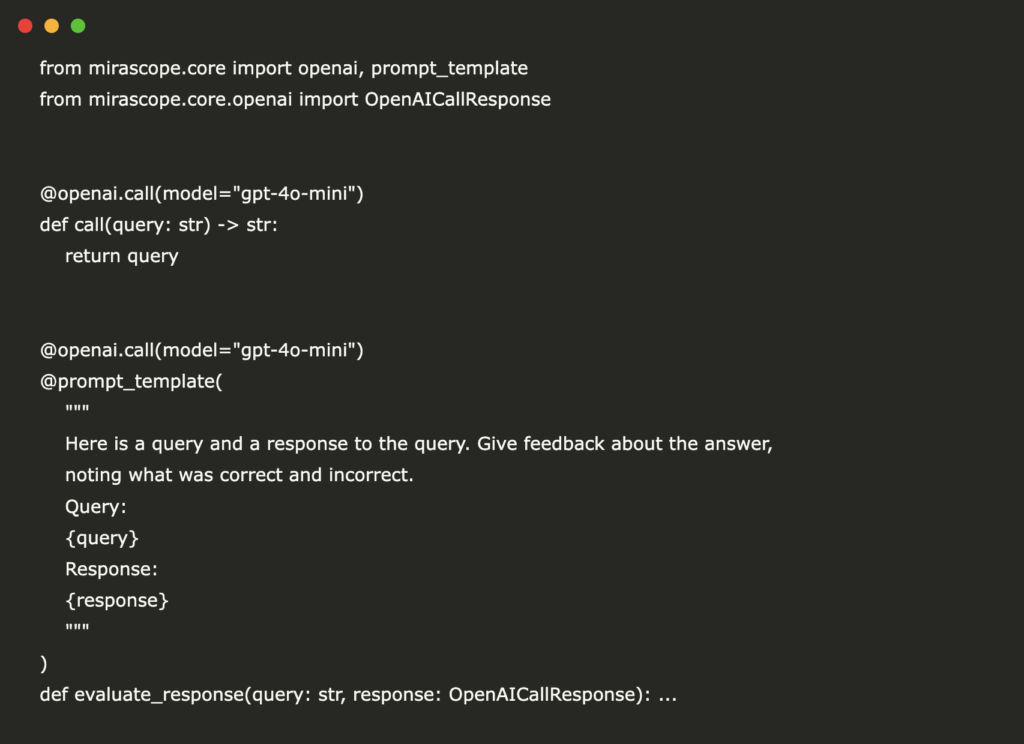
Implementing Self-Refine Technique Using Large Language Models LLMs
Source: MarkTechPost This tutorial demonstrates how to implement the Self-Refine technique using Large Language Models (LLMs) with Mirascope,...
It’s Okay to Be “Just a Wrapper”: Why Solution-Driven AI Companies Win
Source: MarkTechPost In today’s rapidly evolving AI landscape, many founders and observers find themselves preoccupied with the idea...