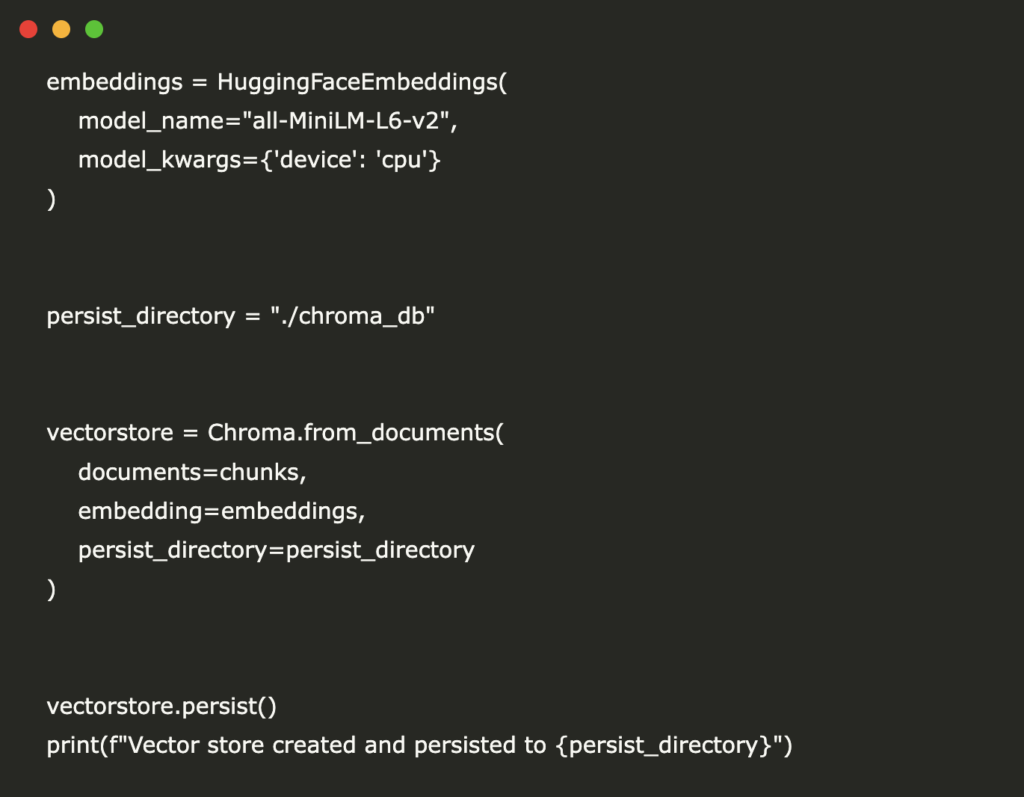
A Code Implementation to Use Ollama through Google Colab and Building a Local RAG Pipeline on Using DeepSeek-R1 1.5B through Ollama, LangChain, FAISS, and ChromaDB for Q&A
Source: MarkTechPost In this tutorial, we’ll build a fully functional Retrieval-Augmented Generation (RAG) pipeline using open-source tools that...
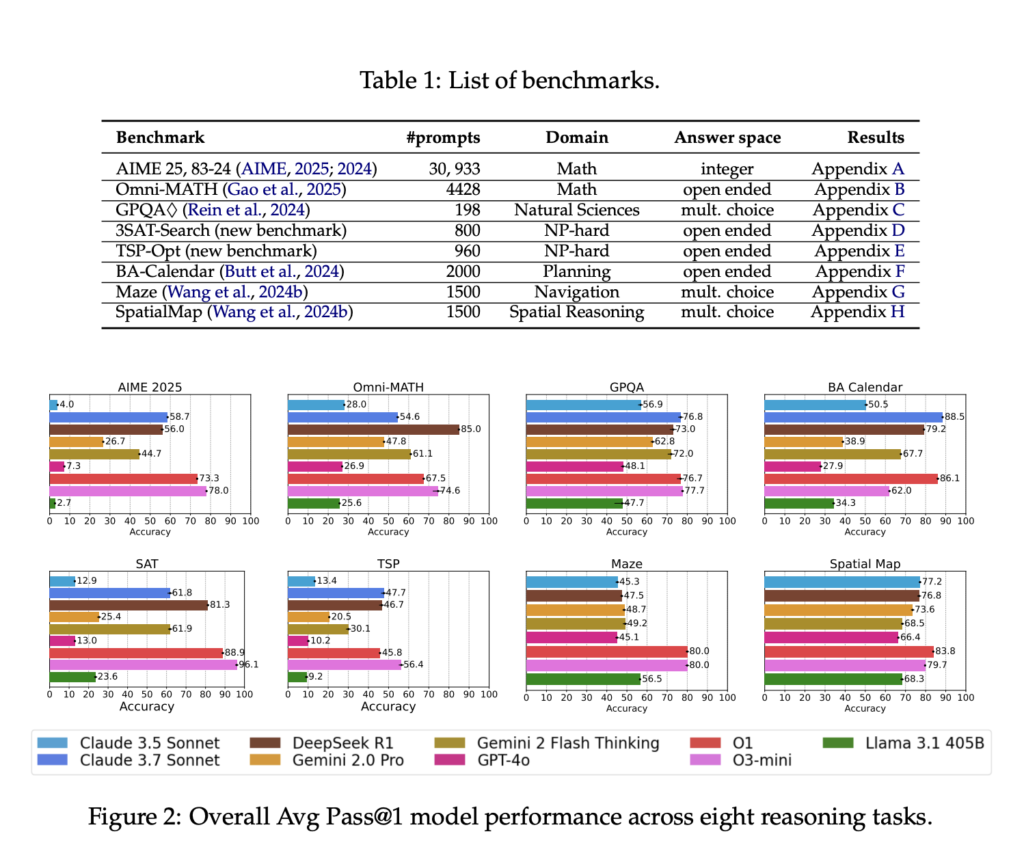
This AI Paper Introduces Inference-Time Scaling Techniques: Microsoft’s Deep Evaluation of Reasoning Models on Complex Tasks
Source: MarkTechPost Large language models are often praised for their linguistic fluency, but a growing area of focus...

RARE (Retrieval-Augmented Reasoning Modeling): A Scalable AI Framework for Domain-Specific Reasoning in Lightweight Language Models
Source: MarkTechPost LLMs have demonstrated strong general-purpose performance across various tasks, including mathematical reasoning and automation. However, they...
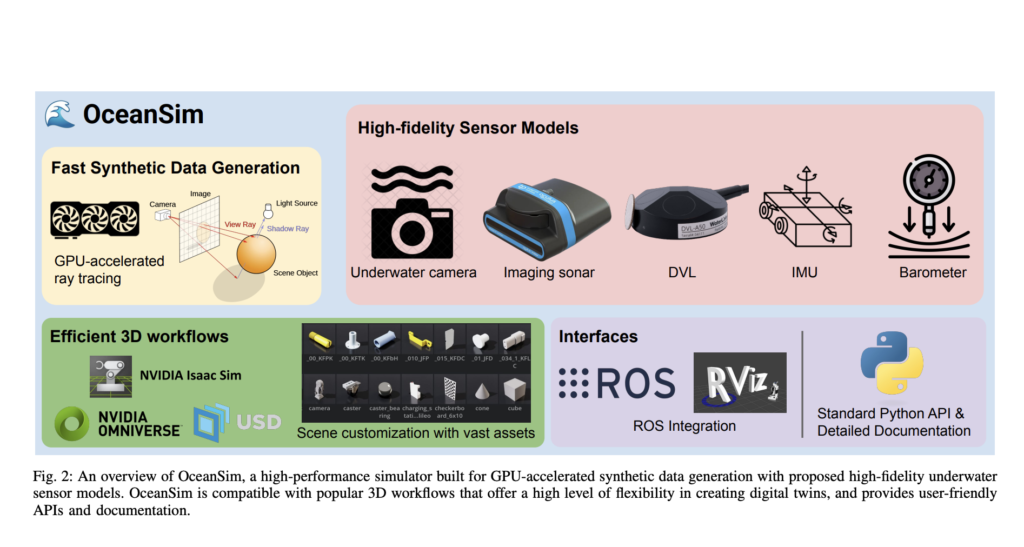
University of Michigan Researchers Introduce OceanSim: A High-Performance GPU-Accelerated Underwater Simulator for Advanced Marine Robotics
Source: MarkTechPost Marine robotic platforms support various applications, including marine exploration, underwater infrastructure inspection, and ocean environment monitoring....
Aditya Prakash, Founder and CEO of SKIDOS – Interview Series
Source: Unite.AI Aditya Prakash is the founder and CEO of SKIDOS, an award-winning edtech company based in Copenhagen,...
Bespoke LLMs for Every Business? DeepSeek Shows Us the Way
Source: Unite.AI Once upon a time, the tech clarion call was “cellphones for everyone” – and indeed mobile communications...

A Step-by-Step Coding Guide to Building a Gemini-Powered AI Startup Pitch Generator Using LiteLLM Framework, Gradio, and FPDF in Google Colab with PDF Export Support
Source: MarkTechPost In this tutorial, we built a powerful and interactive AI application that generates startup pitch ideas...
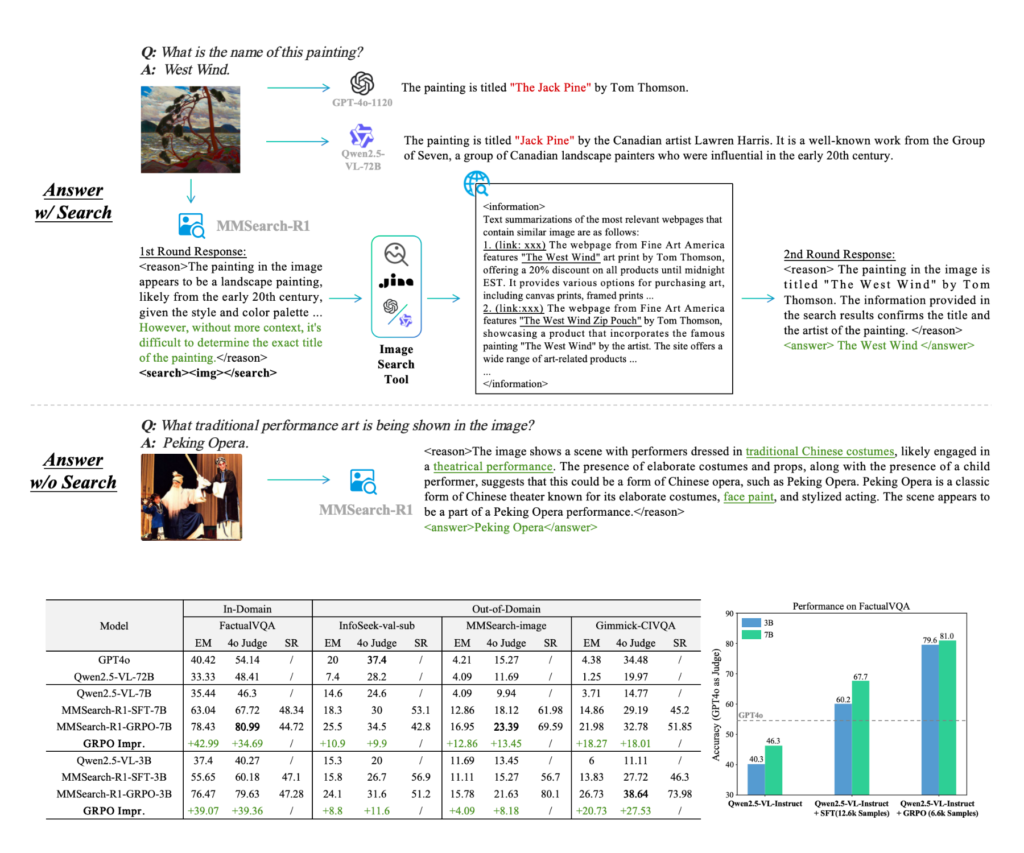
MMSearch-R1: End-to-End Reinforcement Learning for Active Image Search in LMMs
Source: MarkTechPost Large Multimodal Models (LMMs) have demonstrated remarkable capabilities when trained on extensive visual-text paired data, advancing...
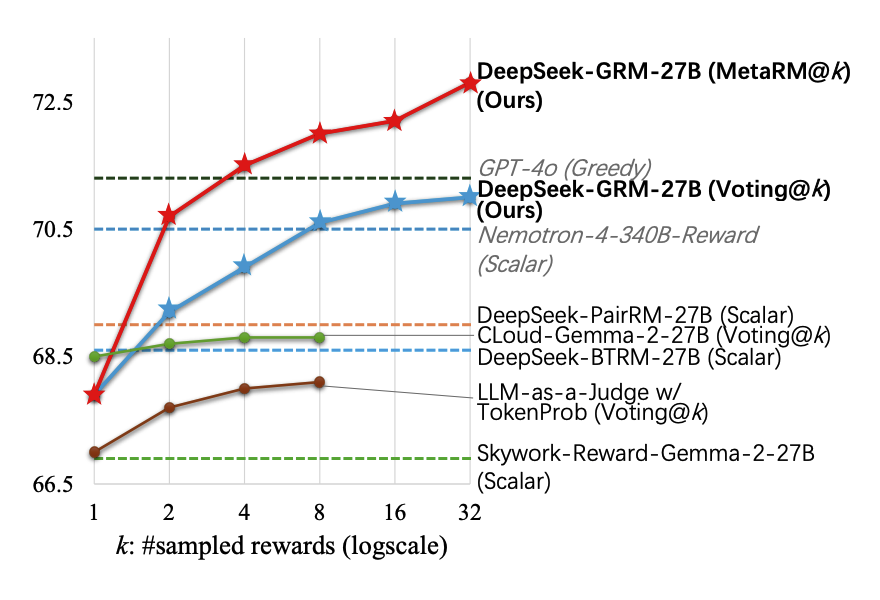
Scalable and Principled Reward Modeling for LLMs: Enhancing Generalist Reward Models RMs with SPCT and Inference-Time Optimization
Source: MarkTechPost Reinforcement Learning RL has become a widely used post-training method for LLMs, enhancing capabilities like human...

Open-Source AI Strikes Back With Meta’s Llama 4
Source: Unite.AI In the past few years, the AI world has shifted from a culture of open collaboration...