Source: Unite.AI
Amazon Web Services announced on November 18, 2026 full fine-tuning (FFT) support for SageMaker AI Serverless Model Customization, and reported 90.0% semantic correctness in a coding experiment using more than 100,000 training examples, while cautioning that aggressive settings caused severe general-knowledge losses.
Customers supply a base model, dataset, and hyperparameters; the service allocates compute and manages checkpoints without requiring GPU provisioning, cluster setup, or distributed-training configuration. In AWS’s SageMaker Python SDK example, switching methods means replacing TrainingType.FULL with TrainingType.LORA, leaving the rest of the job configuration unchanged.
FFT updates every model weight. LoRA instead freezes pretrained weights and inserts low-rank adapter matrices, reducing GPU capacity requirements but limiting updates to a smaller representational space. AWS’s explanation is that full-rank training can capture more complex domain adaptations as datasets grow, rather than simply increasing the number of trainable parameters.
Controlled Coding Tests
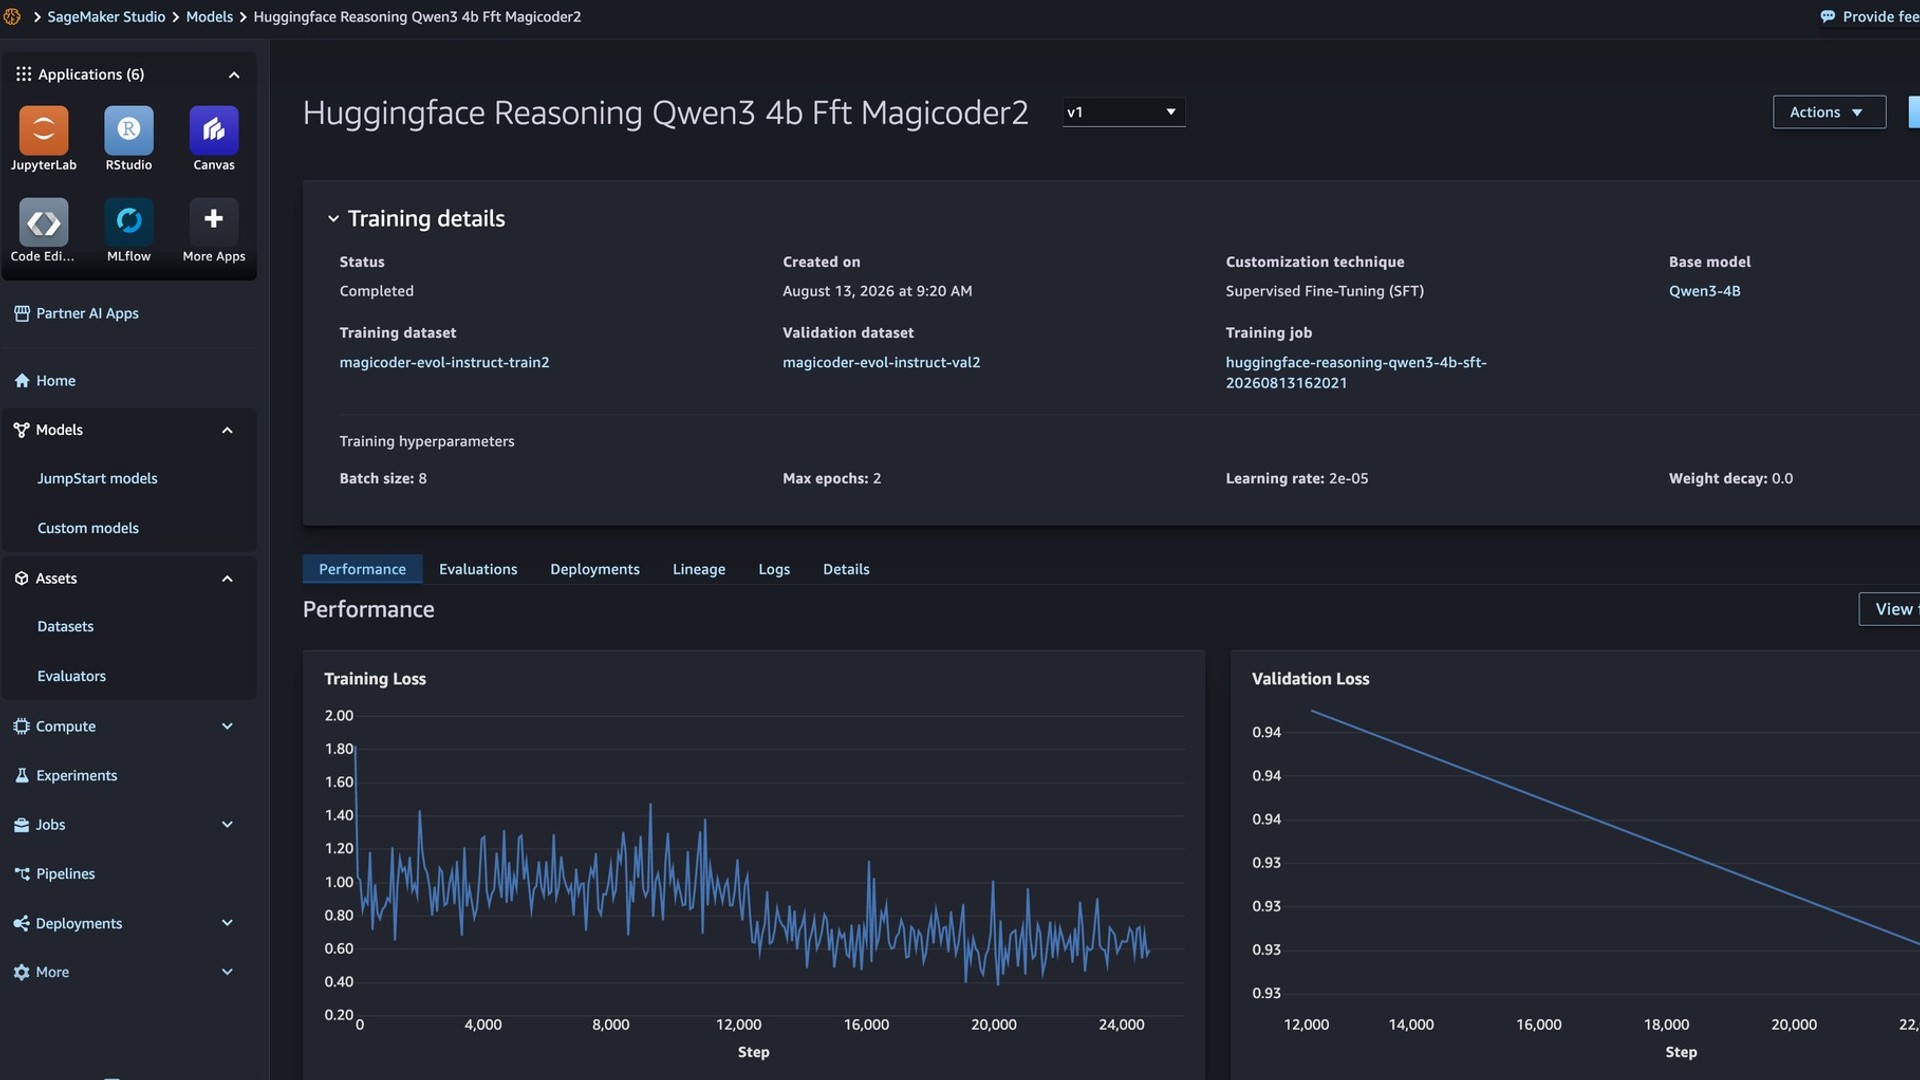
AWS compared the methods using supervised fine-tuning (SFT) of a Qwen3-4B base model, with identical prompts, targets, and evaluation code. The Magicoder-Evol-Instruct-110K dataset supplied coding instruction-response pairs covering algorithm design, debugging, data structures, and systems programming. The split assigned 99,000 records to training, 5,500 to validation, and 5,500 to a held-out test set.
The evaluations separated task performance from knowledge retention. Amazon Nova Pro served as an LLM judge, reading generated code with the original prompt to assess logical correctness. PRIMECODE measured similarity to reference solutions through deterministic BLEU, ROUGE-1/2/L, and F1 metrics, while MMLU tested general knowledge across 57 academic subjects.
AWS reported that its semantic-correctness score peaked at three epochs and that longer training degraded every variant tested. Its radar comparison placed FFT beyond LoRA and the base model on every displayed quality dimension, with the largest leads on BLEU and ROUGE-2, suggesting the difference was not confined to one metric.
AWS said it ran tens of customization experiments across multiple base models, varying learning rate, batch size, warmup ratio, epoch count, and dataset scale; each run from job submission to evaluation took a few hours. Resulting models were automatically registered as versioned Model Packages in SageMaker Model Registry for review or deployment.
Forgetting Risks in Full Fine-Tuning
AWS cautioned that FFT was not universally superior: both FFT and LoRA underperformed the base model on MATH exact match, and a separate LLM-as-Judge comparison favored LoRA at 81.5%, compared with 79.5% for FFT.
Aggressive learning rates caused severe losses. At 5e-5 or higher, MATH scores fell to 2–3% and MMLU accuracy to 3.6% in AWS’s tests, evidence of catastrophic forgetting—the loss of broader capabilities when domain-specific training overwrites pretrained knowledge. Its risk map identified 2e-5 as a safer setting for large datasets; a baseline combining that rate with 5% warmup and a global batch size of 8 best preserved general knowledge as measured by MMLU among the tested configurations.
Batch size also affected retention. At a fixed learning rate, smaller batches generated noisier updates that behaved like a higher learning rate and increased forgetting risk. Larger batches reduced noise but also reduced optimization steps, potentially underfitting the model.
Deployment Trade-Offs
SFT with FFT is available for open-weight models including DeepSeek R1 Distill Qwen 1.5B, Google Gemma 4 26B A4B, and NVIDIA Nemotron 3 Nano 30B (A3B), according to AWS’s supported-model list.
The FFT documentation says the method uses the same dataset formats as LoRA but requires more compute and longer training, produces larger artifacts containing full model weights, and is incompatible with continuous customization. It also removes adapter overhead at inference.
Serverless operation changes who allocates infrastructure and manages checkpoints; it does not reduce the number of weights being trained. The launch therefore makes deeper customization easier to run, while its compute and quality economics still depend on whether task-specific gains outweigh heavier training and any loss of broader capabilities.