Source: Unite.AI
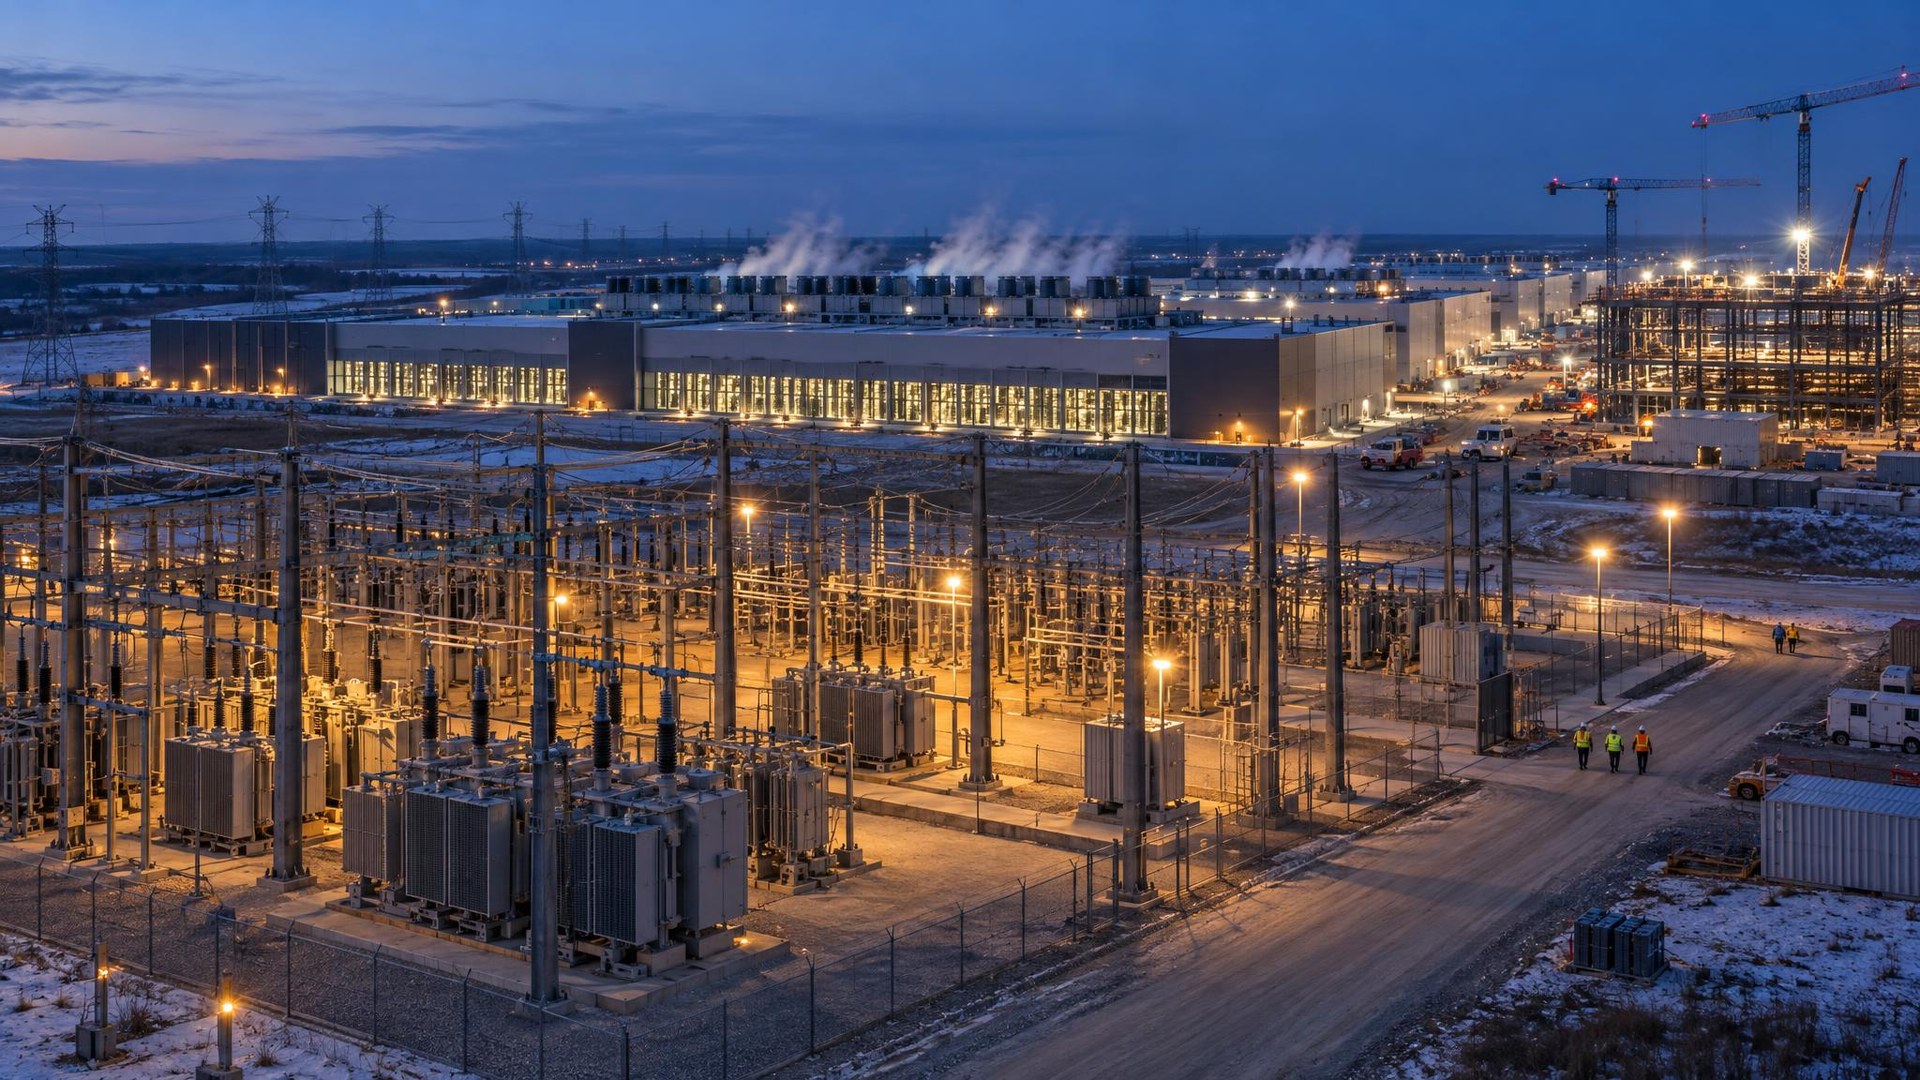
Meta’s engineering team on October 19, 2026 published a detailed technical account of Prometheus, the company’s gigawatt-scale AI supercluster in New Albany, Ohio, confirming its completed first phase trained the Muse foundational models and that Meta plans to scale the system to roughly 1 million GPUs.
In a post on Meta’s engineering blog, Kevin Lee, Yashar Bayani, Ahmed Sharif, and Yee Jiun Song wrote that the first phase trained the Muse family, including the Muse Wonder frontier models, which Meta says deliver state-of-the-art performance on personal and professional agentic tasks. Two years before the disclosure, the New Albany site was a conventional data center running web traffic; Meta reworked it for frontier-model training and is building the supercluster in phases. Prometheus now comprises hundreds of thousands of GPUs spread across traditional and AI-optimized data center buildings and rapid-deployment structures, all operating as a single machine.
Meta reports that it sustained more than 85% goodput on Muse Wonder pre-training runs and more than 90% on reinforcement learning runs, with a wall-clock mean time between interruptions of ~47k GPU hours during training; subsequent fleet-wide changes, including firmware fixes, raised that to more than 54K GPU hours.
Two NVIDIA Platforms in Production
Prometheus deploys two NVIDIA GPU platforms, and Meta says a third based on NVIDIA’s Vera Rubin NVL72 is arriving soon. Each uses an NVL72 rack architecture in which 72 GPUs act as a single accelerator within one network fabric.
The first platform, Catalina, uses the NVIDIA GB200 NVL72 in the Ariel two-rack variant: 36 GPUs per rack are joined over NVLink into a unified 72-GPU domain, each Blackwell GPU paired with a Grace CPU and two ConnectX-7 400G NICs at a 1:1 CPU-to-GPU ratio, delivering 800G of I/O per GPU. Meta says it chose Ariel because the GB200 NVL72 scaled FLOPS, HBM bandwidth, scale-up bandwidth, and scale-up domain size over the H100, while scale-out bandwidth per GPU would have stayed at 400G, an imbalance it expected to cost performance. Catalina runs on Meta’s Open Rack V3 high-power rack design, contributed to the Open Compute Project.
Meta lists Catalina at 72 Blackwell GPUs with 13.4 TB of HBM3e (192 GB per GPU), 720 peak PFLOPS of FP8 training compute (1,440 PFLOPS at FP4), 130 TB/s of peak NVLink bandwidth, 576 TB/s of peak aggregate memory bandwidth, and roughly 120 kW of total system power across the two-rack pair.
The second platform, Clemente, moves to the NVIDIA GB300 NVL72. According to Meta, GB300 raises HBM capacity per GPU by 1.5x, from 192 GB to 288 GB, and dense FP4 throughput by a similar factor, while roughly doubling attention (softmax) acceleration. ConnectX-8 SuperNICs deliver 800G per GPU natively, and a 2:1 GPU-to-CPU ratio lets Clemente pack the full 72-GPU domain into a single rack.
Meta lists Clemente at 72 Blackwell Ultra GPUs with 20.7 TB of HBM3e, over 1 exaFLOP of peak FP4 compute, 130 TB/s of peak NVLink bandwidth (1.8 TB/s bidirectional per GPU), and about 135 kW of rack power, with a stated 5–10% performance improvement over the GB200 NVL72. Clemente can be deployed with modular Air-Assisted Liquid Cooling or with Facility Liquid Cooling in Meta’s newly designed data centers.
Building Fabrics and Regional Aggregation
Alongside the standard data center network, Meta operates a dedicated Ethernet Back-End network for direct GPU-to-GPU communication within and across buildings, designed around the data-parallel hierarchy of large pre-training jobs. Each building-level Ethernet fabric interconnects up to 20,736 GPUs. The initial design used a Disaggregated Scheduled Fabric with sub-packet-level multipath routing and credit-based end-to-end flow control; Meta later updated to a Non-Scheduled Fabric on shallow-buffer 51.2T switches, including Minipack3 with Dynamic Load Balancing and the Spectrum-4-based Minipack3N with NVIDIA’s Adaptive Routing on ConnectX NICs, both running Meta’s FBOSS networking stack.
The Backend Aggregation network, a multi-layer hub-and-spoke design linking building fabrics across 2 km to more than 100 km, is built with Arista 7800-series chassis running deep-buffered Broadcom Jericho3 silicon and delivers multiple Pbps of bandwidth per region pair. Meta says running pre-training over those distances required a dedicated optimization effort with Meta Superintelligence Labs because of speed-of-light constraints. The company describes a physical plant spanning fiber strands that total millions of miles, tens of thousands of switches, and optics in the millions, from 2x400G FR4 LITE short-reach pluggables inside buildings to 800G-ZR coherent optics for links beyond roughly 10 km.
Engineering for Fewer Interruptions
The move from the H100 generation’s NVL8 architecture to NVL72 expanded the scale-up fault domain (the set of GPUs tightly coupled over NVLink for tensor parallelism) from eight GPUs to 72, a 9x larger blast radius, per the post. Because training parallelism maps most efficiently onto power-of-two group sizes, each NVL72 domain runs a 64-GPU slice and keeps eight GPUs as in-rack spares, with roughly 2% additional racks held in reserve. For a 32,768 active-GPU training run, that means provisioning 523 NVL72 racks, or 37,656 GPUs, about 13% above the active footprint; Meta says most of that margin (11%) falls out of the 64-of-72 slice geometry rather than an absolute reliability tax. Each domain incorporates 5,184 tuned differential-pair signaling links at 200 Gbps, crossing GPU SerDes, compute tray PCBs, cable cartridges, and switch tray interfaces.
Fault recovery uses two mechanisms: Parallelism-Aware Fault Tolerance takes a faulty data-parallel replica offline while the rest of the cluster repeats the step and continues training, and distributed asynchronous checkpointing with delta checkpointing and in-memory staging restores the job from its last saved state when a fault’s blast area exceeds one replica.
During Prometheus’s initial phase in mid-2025, interruptions peaked at nearly 1,000 events per 8K GPUs daily. Meta reports a 99% reduction after a year of cross-functional engineering and states its reliability north star is two interruptions per 8K GPUs per day, or ~100k GPU hours MTBI.
Targeted fixes addressed NVLink signal integrity across more than 600,000 connections, HBM and LPDDR memory reliability through refined firmware settings and predictive retirement of degrading devices, NVLink switch health monitored at millisecond resolution, and transparent rerouting of backend link events. Meta also built firmware bundle automation that deploys fixes to more than 100k GPUs within hours and cut the P90 single-pod upgrade time from more than seven hours to two hours, and it describes a co-engineering model in which NVIDIA teams are embedded at its data centers with shared telemetry and joint triage.
Power, Cooling, and Expansion Plans
Synchronized training triggers power transients of 30–40% within the cluster, and starting or pausing a major job can shift loads of more than tens of megawatts in seconds. Meta’s Dynamo Dimmer framework gradually adjusts GPU power limits as the cluster nears its electrical ceiling instead of hard-stopping workloads, backed by rack-level battery backup modules, capacitor trays, facility battery energy storage, and coordination with utility providers.
Cooling mixes modular air-assisted liquid cooling in free-air buildings and rapid-deployment structures with facility liquid cooling in the purpose-built AI-optimized building, and Meta also integrates leased capacity from strategic partners. The company states it pays the full cost of energy for the New Albany site and matches its energy use with new clean and renewable energy, uses direct-to-chip closed-loop liquid cooling in its newest AI-optimized data centers, and shares designs such as its IcePack liquid-cooled network rack through the Open Compute Project.
Meta plans to expand Prometheus with a mix of GB300 NVL72 and Vera Rubin NVL72 systems. Its upcoming San Miguel platform is listed with 72 Vera Rubin GPUs carrying 288 GB of HBM4 and 19.2 TB/s of peak bandwidth per GPU, 2.52 peak EFLOPS of FP4 training compute (1.26 EFLOPS FP8) per rack, 216 TB/s of peak NVLink bandwidth (3 TB/s bidirectional per GPU), roughly 1,500 TB/s of peak aggregate memory bandwidth, and fully liquid-cooled compute trays at over 170 kW per rack, with a Meta-stated 10–20% performance-per-watt improvement over the GB300 NVL72.
Hyperion, Meta’s next supercluster in Richland Parish, Louisiana, is being designed from the ground up with insights from Prometheus, with closed-loop liquid cooling, full grid connectivity with utility partner Entergy for which Meta says it pays the full cost, and next-generation network designs.